EPIK: Precise and scalable evolutionary placement with informative k-mers
Warning: file_get_contents(): php_network_getaddresses: getaddrinfo for api.crossref.org failed: No address associated with hostname in /var/www/html/atgc/wp-content/themes/atgc-wp-theme/inc/atgc-get-doi-metadata.php on line 77
Warning: file_get_contents(https://api.crossref.org/works/10.1093/bioinformatics/btad692): Failed to open stream: php_network_getaddresses: getaddrinfo for api.crossref.org failed: No address associated with hostname in /var/www/html/atgc/wp-content/themes/atgc-wp-theme/inc/atgc-get-doi-metadata.php on line 77
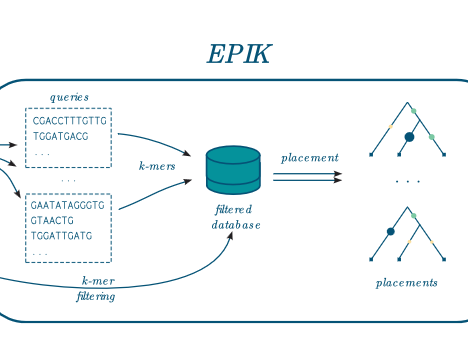
EPIK is a program dedicated to « Phylogenetic Placement » (PP) of metagenomic or metabarcoding reads on a reference tree.
It is similar in spirit and technically the successor of RAPPAS (Linard et al. 2020). EPIK achieves identical or slightly better accuracy than RAPPAS and outperforms it in speed and flexibility. In many aspects the documentation of RAPPAS remains valid.
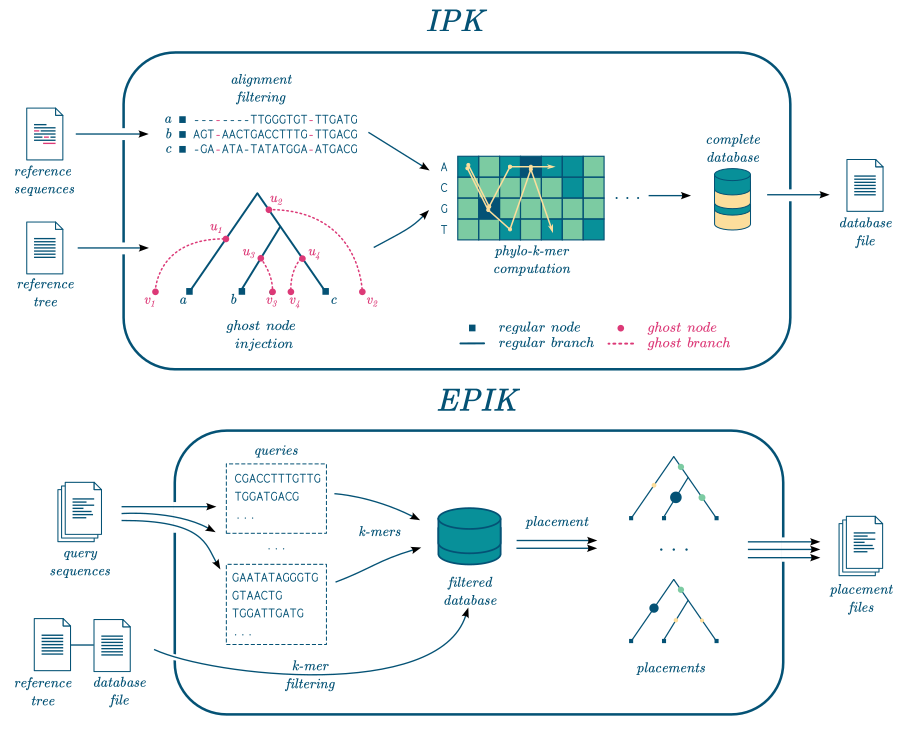
EPIK takes as input a file containing database of phylo-k-mers built with IPK and a set of reads to place on the related phylogeny. It works for nucleotidic and amino-acid query sequences.
EPIK can filter the database to load only the most informative phylo-k-mers, which reduces the memory usage.
EPIK can also run in parallel.
Keywords
Phylogenetic placement, metabarcoding, taxonomic identification, NGS, software
Other tools
dipwmsearch
Protein binding sites in DNA or RNA sequences are modeled by probabilistic motifs. A Position Weight Matrix (PWM) is a simple, powerful, and widely used representation of such motifs. Because PWMs assume that sequence positions are independent of eachother (which is too restrictive for some binding or interaction sites), a generalisation of PWMs, termed di-nucleotidic…
DExTER
Overview DExTER (Domain Exploration To Explain gene Regulation) is a bioinformatics tool designed to automatically identify genomic regions whose nucleotide composition correlates with gene expression levels. Unlike traditional approaches focusing on short transcription factor binding sites (6-12 bp), DExTER detects Long Regulatory Elements (LREs) that can span tens to hundreds of nucleotides. This makes it…
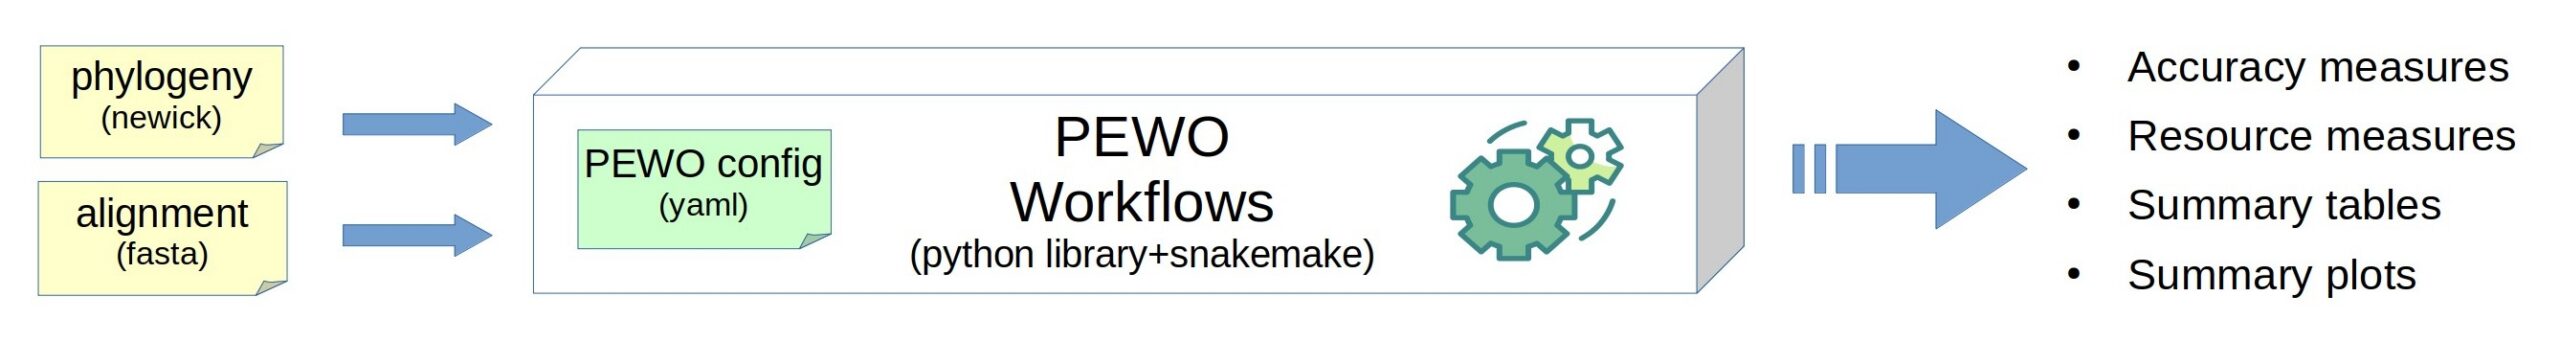
PEWO: a collection of workflows…
Introduction and context In the Bioinformatics team of the LIRMM (CNRS & Univ. Montpellier), we develop a series of tools for metagenomics / metabarcoding analysis. Our tools exploit phylo-k-mers (which are k-mers combined with phylogenetic information) computed for an input set of reference sequences and their phylogeny. The phylo-k-mers are computed and indexed with IPK,…