PhyML
Overview: new algorithms, methods and utilities PhyML is a software package that uses modern statistical approaches to build phylogenetic trees from the analysis of alignments of nucleotide or amino acid sequences. The main tool in this package builds phylogenies under the maximum likelihood criterion. It implements a large number of substitution models coupled to efficient…
SMS: Smart Model Selection in…
SMS (Smart Model Selection) automatically selects the best-fitting evolutionary model for an alignment of DNA or protein sequences. It compares substitution models using the AIC or BIC statistical criteria to support phylogenetic tree reconstruction with PhyML.
FastME
FastME is a software package for the fast and accurate inference of phylogenetic trees from distance matrices. It implements algorithms based on the Balanced Minimum Evolution (BME) principle, a distance-based criterion closely related to the Neighbor Joining (NJ) method. The goal of the BME framework is to identify the phylogenetic tree that minimizes the total…
ERaBLE: Evolutionary Rates and Branch…
ERaBLE estimates branch lengths and relative gene evolutionary rates from a reference phylogeny and a collection of gene distance matrices. It provides a way to add evolutionary distance information to a topology obtained from a previous phylogenetic analysis. What does ERaBLE do? ERaBLE takes one distance matrix per gene and a tree describing the relationships…
dipwmsearch
Protein binding sites in DNA or RNA sequences are modeled by probabilistic motifs. A Position Weight Matrix (PWM) is a simple, powerful, and widely used representation of such motifs. Because PWMs assume that sequence positions are independent of eachother (which is too restrictive for some binding or interaction sites), a generalisation of PWMs, termed di-nucleotidic…
EPIK: Precise and scalable evolutionary…
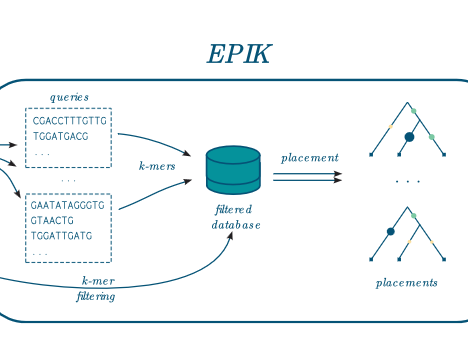
EPIK is a program dedicated to « Phylogenetic Placement » (PP) of metagenomic or metabarcoding reads on a reference tree. It is similar in spirit and technically the successor of RAPPAS (Linard et al. 2020). EPIK achieves identical or slightly better accuracy than RAPPAS and outperforms it in speed and flexibility. In many aspects the documentation of RAPPAS…
TFscope
Characterizing the binding preferences of transcription factors (TFs) in different cell types and conditions is key to understand how they orchestrate gene expression. TFscope is a machine learning approach that identifies sequence features explaining the binding differences observed between two ChIP-seq experiments targeting either the same TF in two conditions or two TFs with similar…
AQUAPONY
AquaPony: interactive visualization of phylogeographic scenarios AquaPony is a web application designed to explore and interpret evolutionary scenarios on annotated phylogenetic trees (for example, ancestral geographic states). It was built to make uncertainty in ancestral reconstructions easier to understand and communicate. Why AquaPony? In phylogeography, several scenarios can be nearly as plausible as the best…
DExTER
Overview DExTER (Domain Exploration To Explain gene Regulation) is a bioinformatics tool designed to automatically identify genomic regions whose nucleotide composition correlates with gene expression levels. Unlike traditional approaches focusing on short transcription factor binding sites (6-12 bp), DExTER detects Long Regulatory Elements (LREs) that can span tens to hundreds of nucleotides. This makes it…