TFscope
Characterizing the binding preferences of transcription factors (TFs) in different cell types and conditions is key to understand how they orchestrate gene expression. TFscope is a machine learning approach that identifies sequence features explaining the binding differences observed between two ChIP-seq experiments targeting either the same TF in two conditions or two TFs with similar motifs (paralogous TFs). TFscope systematically investigates differences in the core motif, nucleotide environment and co-factor motifs, and provides the contribution of each key feature in the two experiments.
TFscope online execution
Execution API: Checking…
Other tools
DExTER
Overview DExTER (Domain Exploration To Explain gene Regulation) is a bioinformatics tool designed to automatically identify genomic regions whose nucleotide composition correlates with gene expression levels. Unlike traditional approaches focusing on short transcription factor binding sites (6-12 bp), DExTER detects Long Regulatory Elements (LREs) that can span tens to hundreds of nucleotides. This makes it…
dipwmsearch
Protein binding sites in DNA or RNA sequences are modeled by probabilistic motifs. A Position Weight Matrix (PWM) is a simple, powerful, and widely used representation of such motifs. Because PWMs assume that sequence positions are independent of eachother (which is too restrictive for some binding or interaction sites), a generalisation of PWMs, termed di-nucleotidic…
PEWO: a collection of workflows…
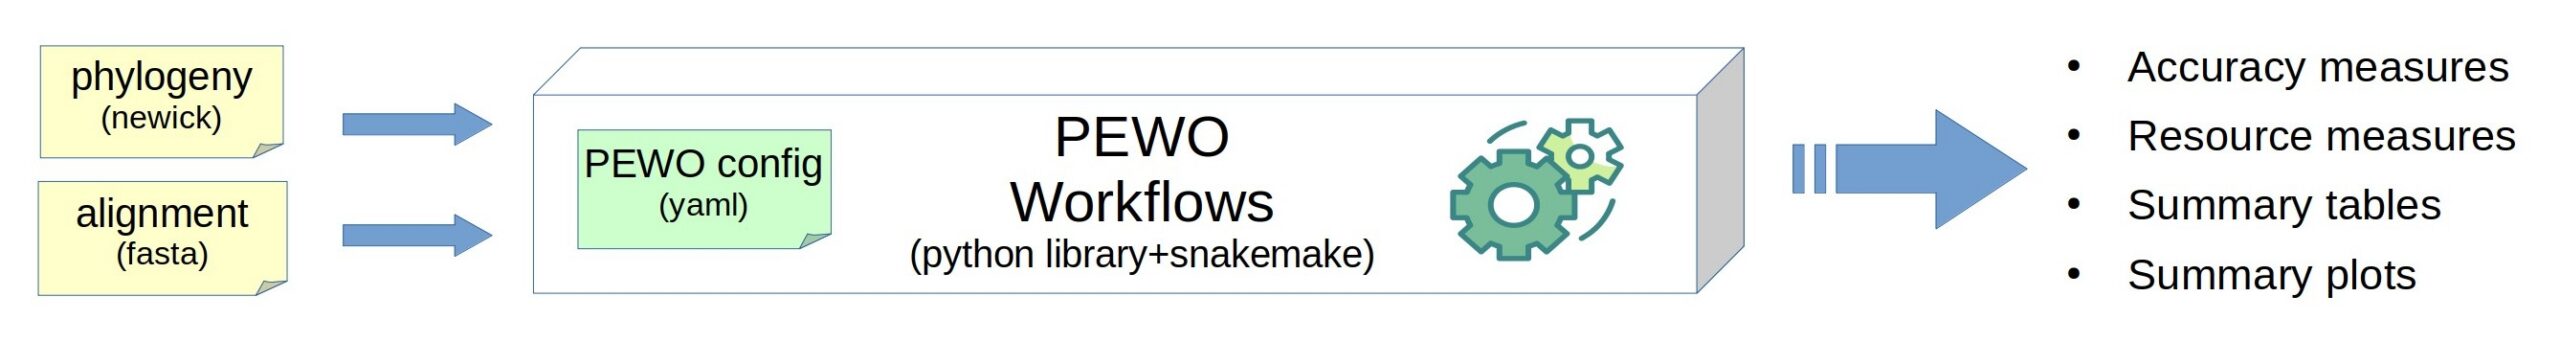
Introduction and context In the Bioinformatics team of the LIRMM (CNRS & Univ. Montpellier), we develop a series of tools for metagenomics / metabarcoding analysis. Our tools exploit phylo-k-mers (which are k-mers combined with phylogenetic information) computed for an input set of reference sequences and their phylogeny. The phylo-k-mers are computed and indexed with IPK,…