EPIK: Precise and scalable evolutionary placement with informative k-mers
EPIK is a program dedicated to « Phylogenetic Placement » (PP) of metagenomic or metabarcoding reads on a reference tree.
It is similar in spirit and technically the successor of RAPPAS (Linard et al. 2020). EPIK achieves identical or slightly better accuracy than RAPPAS and outperforms it in speed and flexibility. In many aspects the documentation of RAPPAS remains valid.
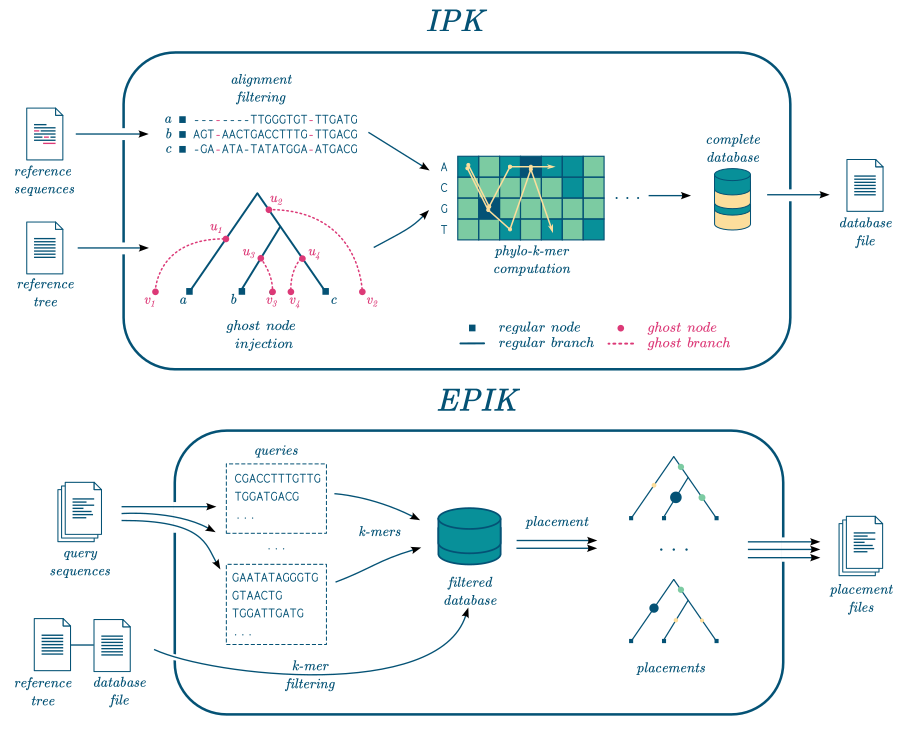
EPIK takes as input a file containing database of phylo-k-mers built with IPK and a set of reads to place on the related phylogeny. It works for nucleotidic and amino-acid query sequences.
EPIK can filter the database to load only the most informative phylo-k-mers, which reduces the memory usage.
EPIK can also run in parallel.
Keywords
Phylogenetic placement, metabarcoding, taxonomic identification, NGS, software
Other tools
WAVES
Warning : This application is no longer maintained and out of date. If you’re interested in, just have a look to MYST Summary WAVES is a web application dedicated to bioinformatic tool integration. It provides an efficient way to implement a service for any bioinformatic software. Such services are automatically made available in three ways:…
FastME
FastME is a software package for the fast and accurate inference of phylogenetic trees from distance matrices. It implements algorithms based on the Balanced Minimum Evolution (BME) principle, a distance-based criterion closely related to the Neighbor Joining (NJ) method. The goal of the BME framework is to identify the phylogenetic tree that minimizes the total…
RSCU_RS: Measuring the bias in…
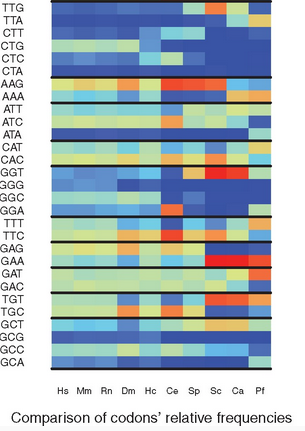
Overview Overview: In the protein coding sequences of a species, the 61 possible codons of the genetic code are not equally distributed. This observation is referred to as the Codon Usage Bias (CUB) of a species. Several measures have been proposed to quantify the CUB using the frequencies of codons in all RNA coding sequences…